AI Crawlers, robots.txt and llms.txt for WordPress Stores: Who to Let In (2026)
Which AI bots to let into a WordPress or WooCommerce store, which you may block, the robots.txt rules to use, and what llms.txt is really for.
A WordPress store should allow the AI bots that bring citations (search bots and on-demand assistants such as OAI-SearchBot, ChatGPT-User, PerplexityBot, Claude-SearchBot, Claude-User, Googlebot, Bingbot, Applebot) and may block the training-only bots (GPTBot, ClaudeBot, Applebot-Extended, CCBot, Bytespider and others) at no visibility cost. An engine that cannot read a page cannot cite it, so "block every AI bot" switches off AI visibility. llms.txt is a Markdown map of the site for language models: harmless, cheap, and not something any major engine has said it reads.
Want to know if AI assistants recommend your site? Free scan, about a minute →
This guide uses a demo WooCommerce store (Northbean Coffee Supply) with the CiteProof plugin. The plugin writes the rules and the file; the reasoning is the same if you edit robots.txt by hand.
Why a blocked bot means no citation
Every bot, search engine or AI, reads one file before anything else: robots.txt. Most WordPress stores are in one of two states. Either the file has no rule for AI bots, so they can read everything, or a plugin or a hosting default added a rule that blocks every AI crawler, and nobody remembers it.
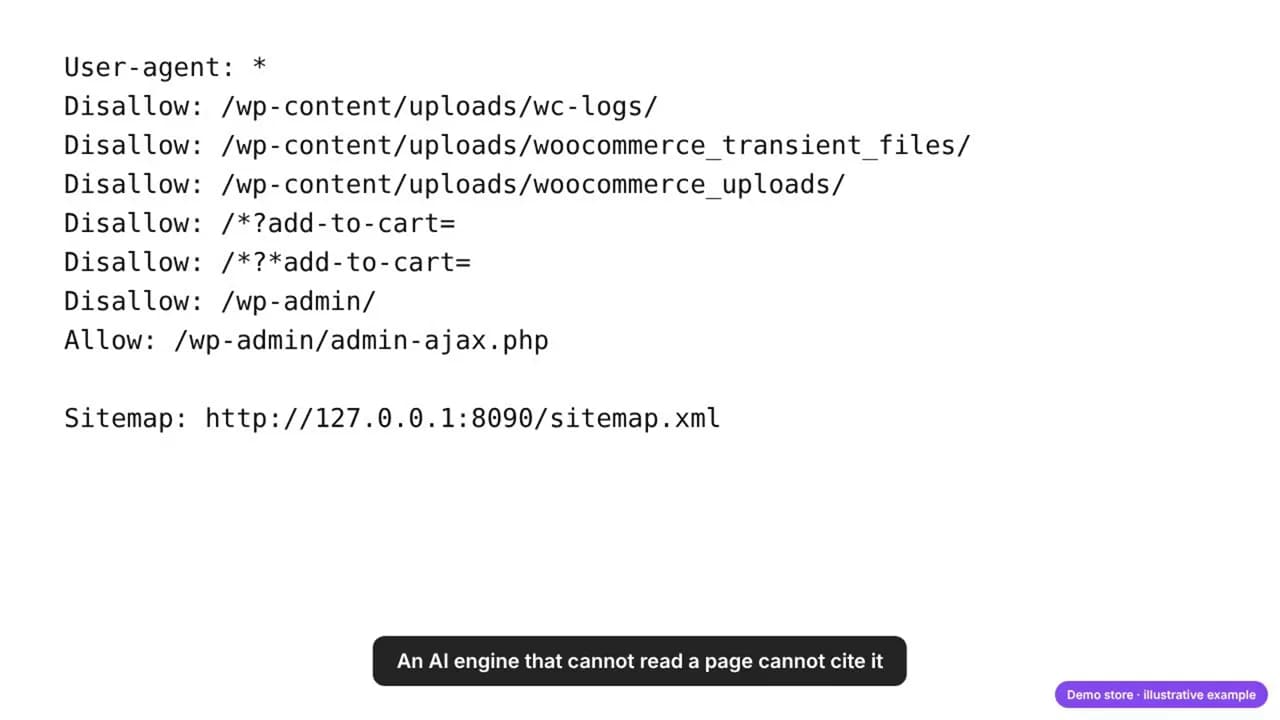
The effect is mechanical. When a user asks ChatGPT, Perplexity or Claude a question, the engine fetches a handful of pages before it answers, and names them as sources. A page it cannot fetch cannot be a source, whatever else you fixed on it: schema, descriptions, policies. Crawler access is the first check in answer engine optimization (AEO), before any content work.
The two kinds of AI bots
The mistake is treating all AI bots as one thing. They come in two groups, with different purposes and different consequences.
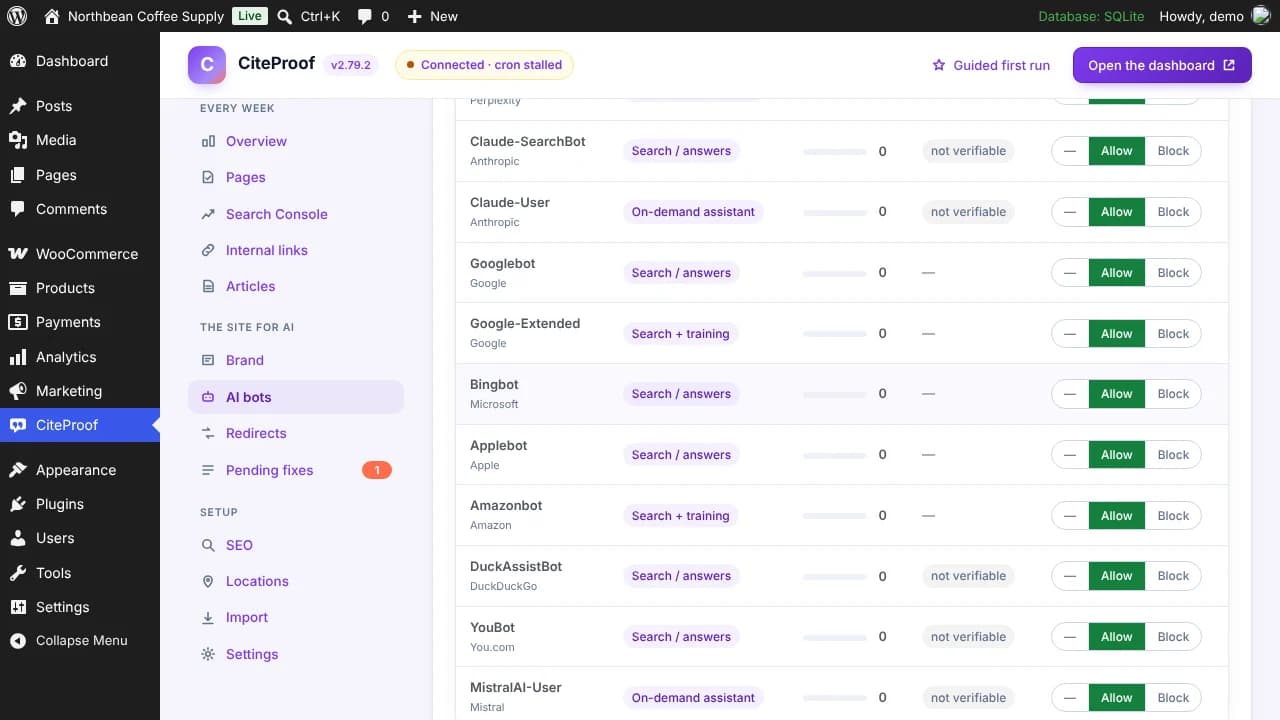
Bots that bring citations. Search bots and on-demand assistants: they fetch pages to answer a question, now, and the answer links to what they fetched. The purposes below come from each operator's own documentation: OpenAI [1], Anthropic [2] and Google [3].
| Bot | Operator | Purpose |
|---|---|---|
| OAI-SearchBot | OpenAI | Search / answers |
| ChatGPT-User | OpenAI | On-demand assistant |
| PerplexityBot | Perplexity | Search / answers |
| Perplexity-User | Perplexity | On-demand assistant |
| Claude-SearchBot | Anthropic | Search / answers |
| Claude-User | Anthropic | On-demand assistant |
| Googlebot | Search / answers (and AI Overviews) | |
| Bingbot | Microsoft | Search / answers (and Copilot) |
| Applebot | Apple | Search / answers |
| Amazonbot | Amazon | Search and training |
| DuckAssistBot | DuckDuckGo | Search / answers |
| YouBot | You.com | Search / answers |
| MistralAI-User | Mistral | On-demand assistant |
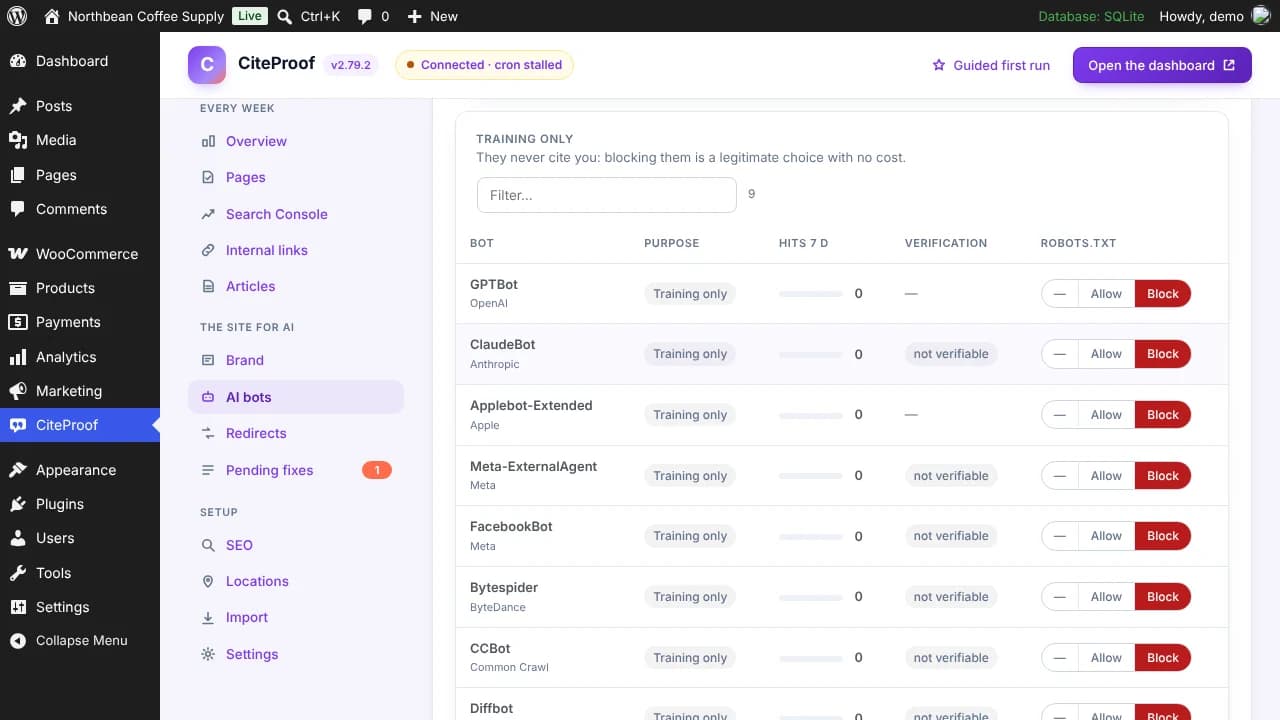
Training-only bots. They collect text to train models. They never cite you, and blocking them changes nothing about whether an answer names your store.
| Bot | Operator | Purpose |
|---|---|---|
| GPTBot | OpenAI | Training only |
| ClaudeBot | Anthropic | Training only |
| Google-Extended | Gemini training and grounding in the Gemini app; does not affect inclusion or ranking in Google Search. Not training-only: blocking it can take you out of Gemini's answers | |
| Applebot-Extended | Apple | Training only |
| Meta-ExternalAgent, FacebookBot | Meta | Training only |
| Bytespider | ByteDance | Training only |
| CCBot | Common Crawl | Training only |
| Diffbot | Diffbot | Training only |
| cohere-ai | Cohere | Training only |
Blocking the first group switches off AI visibility. Blocking the second is a legitimate choice with no visibility cost: a matter of policy, not of SEO.
The preset: search yes, training no
You do not have to decide bot by bot. In the plugin, under AI bots, one preset, "Recommended: search yes, training no", opens the first group and closes the second. The table fills in and the box on the right shows exactly what will be written in robots.txt. Nothing changes until you press Save the rules. Google, Bing and Apple always stay allowed, because blocking them takes the store out of search.
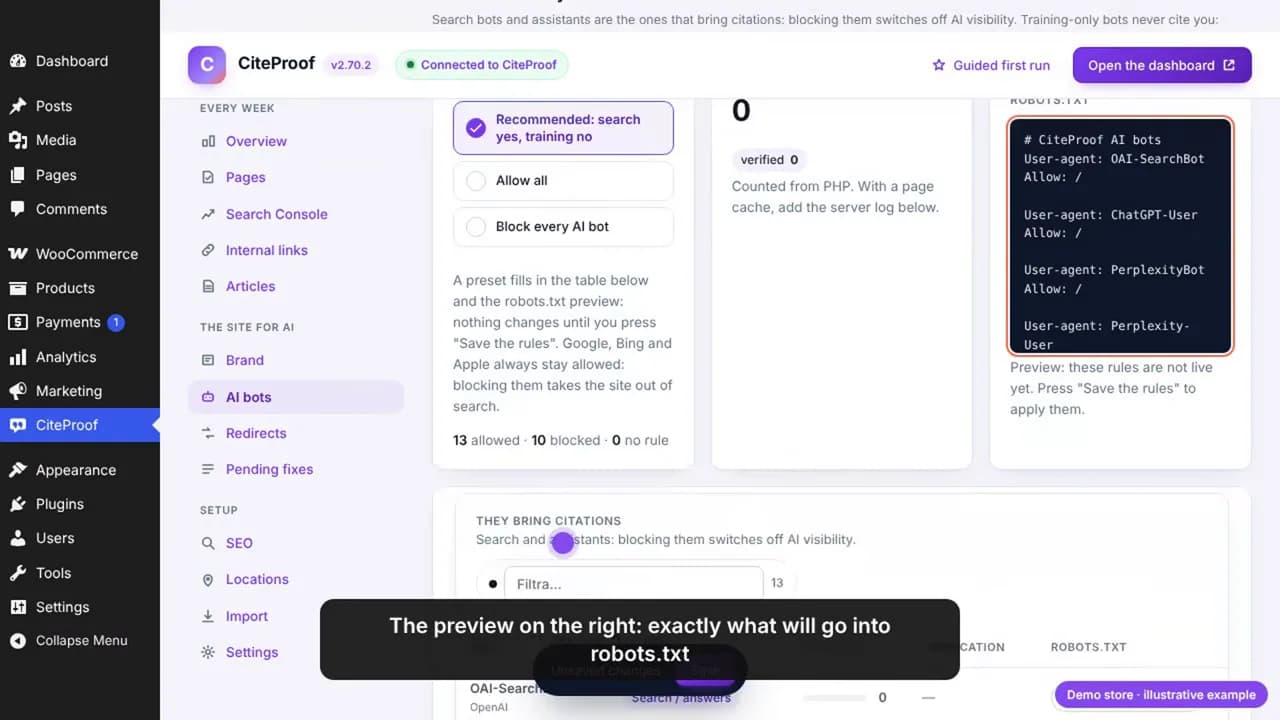
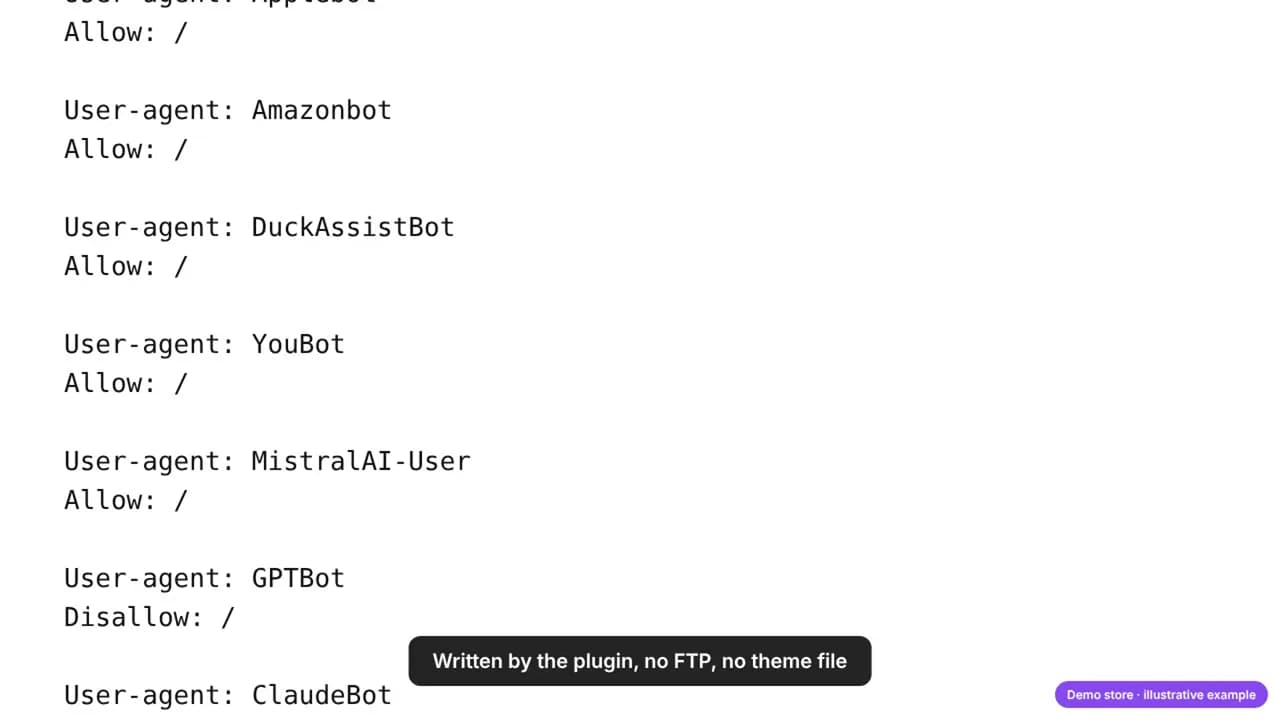
The rules the plugin writes, in robots.txt terms, look like this for the main bots: the bots that bring citations allowed, the training-only bots blocked, then the sitemap (the plugin writes one block for every bot in both tables; replace the sitemap address with yours):
User-agent: OAI-SearchBot
Allow: /

User-agent: ChatGPT-User
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: Claude-User
Allow: /

User-agent: Googlebot
Allow: /

User-agent: Bingbot
Allow: /

User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: Google-Extended
Allow: /

Sitemap: https://yourstore.com/wp-sitemap.xml
The search and assistant bots get an explicit Allow, so the permission survives any catch-all rule another plugin may add; the training-only bots get Disallow; Google-Extended stays allowed, because it also governs the answers of the Gemini app (see the table above); the sitemap line stays there for everyone. The plugin serves this on every request, so there is no file to upload and nothing to edit when a new bot appears: the list updates with the plugin. If you edit robots.txt by hand, the same rules apply; keep in mind that a Disallow: / under User-agent: * blocks everyone, including Googlebot.
Check what you already have. A "block AI" plugin setting or hosting template that lists OAI-SearchBot or PerplexityBot next to GPTBot is the setting that costs citations. The free scan reads your current robots.txt and names the bots it blocks.
Who actually reads the store: verification and the log
A rule is only half of it. The plugin records every visit by an AI bot: which bot, which page, when. For the bots whose operators publish their address ranges, the visit is verified against those ranges, so a scraper pretending to be Googlebot does not count. Bots whose ranges are not published are marked "not verifiable".
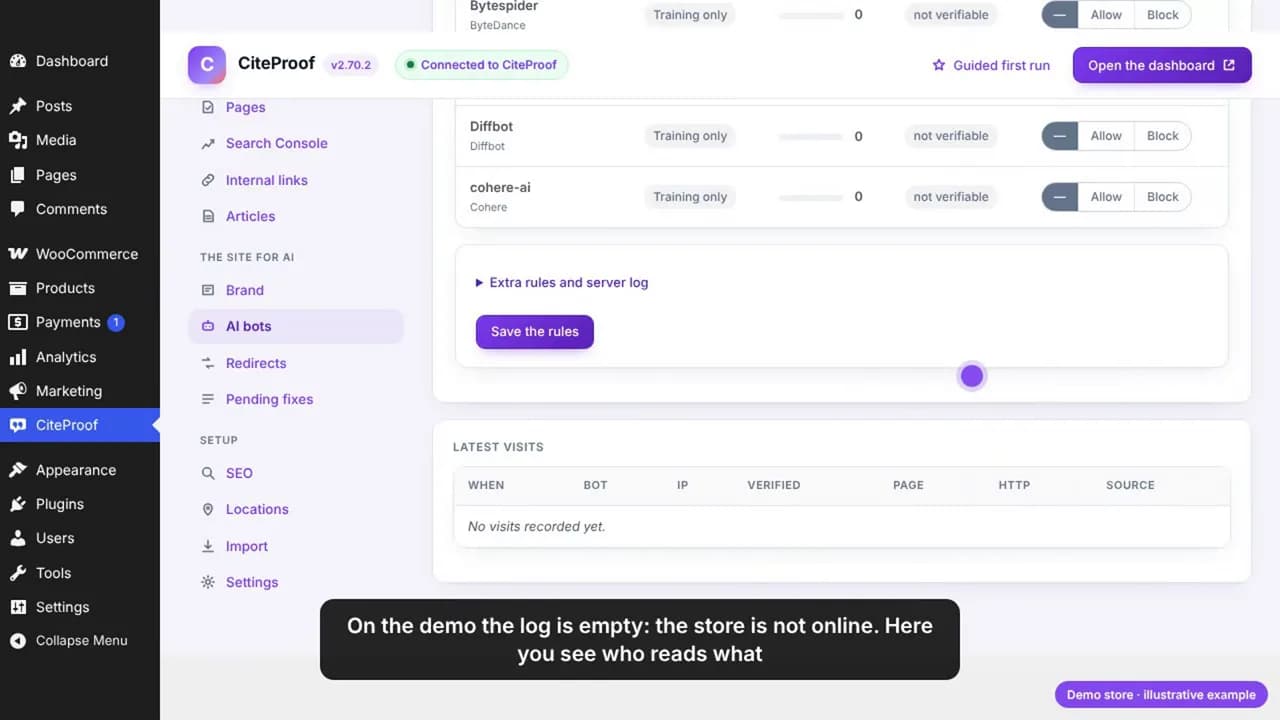
On a live store this log is where you learn which pages the engines actually read this week, and which important pages they never touched. With a page cache in front of WordPress, the PHP counter sees fewer visits: add the server log and the plugin reads it from there.
What llms.txt is, and what it is not
llms.txt is a Markdown file at the root of the site, a short map written for language models: the name of the store as a heading, a one-line summary, then lists of links to the main pages, the recent articles, the product categories [4]. The format, its origin and who reads it are covered in what llms.txt is. The plugin generates it from the site content and refreshes it daily, so it never goes stale, and it is served virtually: no file on disk, so it works on read-only hosts. For a site without the plugin, the free llms.txt generator scans the site and builds the file from its real URLs, ready to upload to the root.
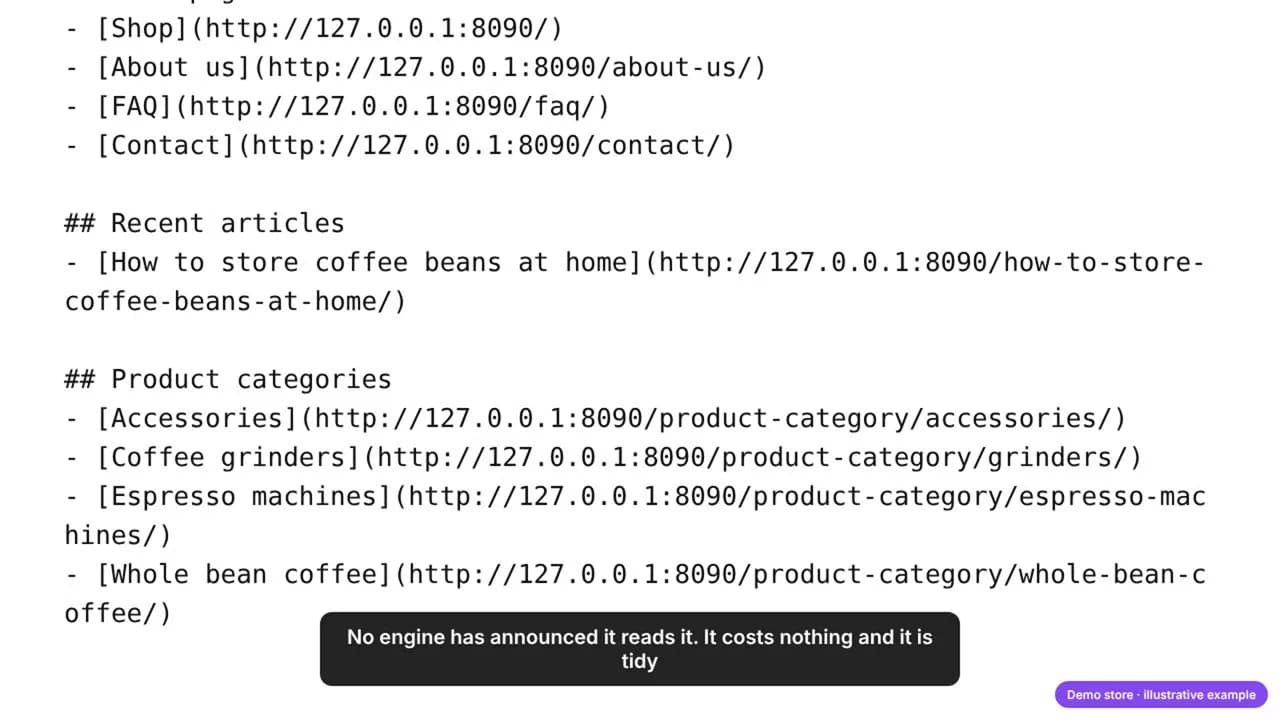
Be precise about what it is worth. No major AI engine has said that it reads this file, and Google says Google Search, its AI features included, doesn't use it [5]. So it does not move a score and it does not replace the content on the pages. It costs nothing, some customers and tools check for it, and a tidy one does no harm. What actually gets a page discovered is a link to it from a page that is already read.
The plugin's Overview crosses the visit log with your content and lists the important pages no AI has read. Three actions, in the order they matter: link them from the pages that are read; send them to IndexNow, the protocol Bing and others use to pick up new addresses; put them at the top of llms.txt.
Where it all lives
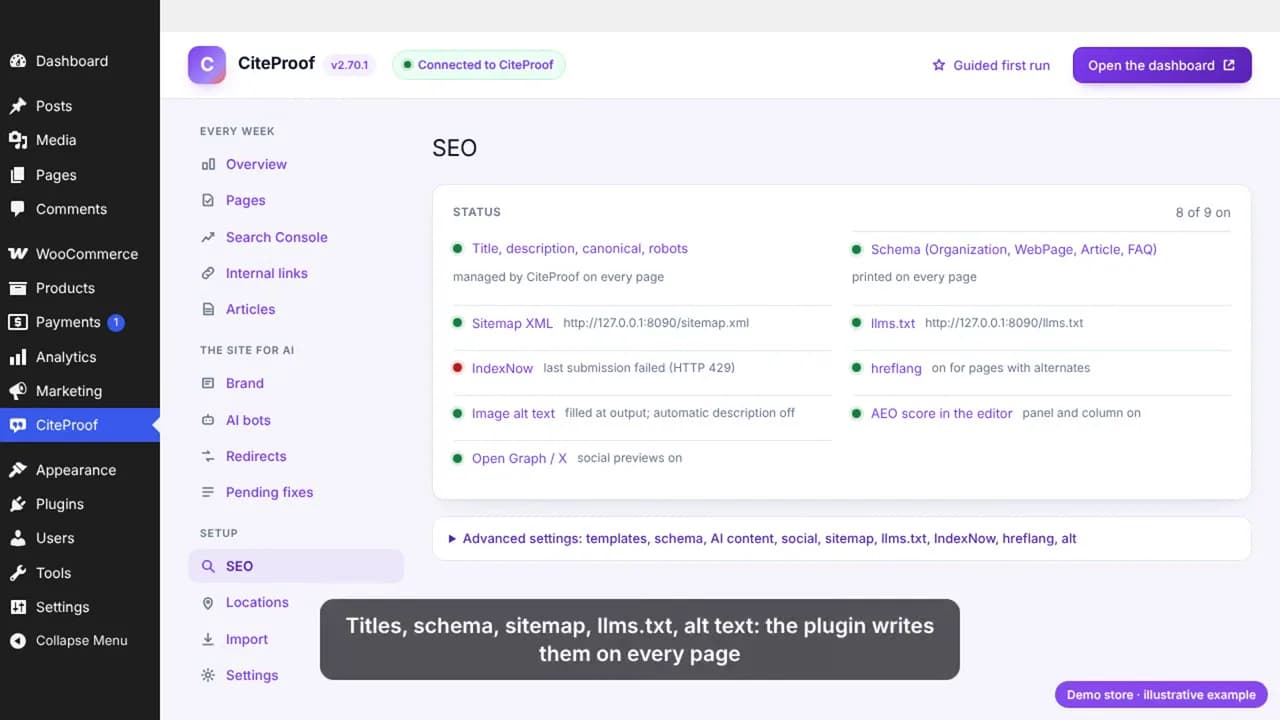
Everything in this guide is one screen in the plugin: the SEO status shows robots rules, sitemap, llms.txt, IndexNow and the schema, each on or off, each with its link. Nothing is written to the theme and nothing needs FTP. Check that screen and the bot log once a month; that is all the maintenance there is.
Which AI bots does your store block today?
The CiteProof free scan reads your robots.txt and your pages the way the engines do, and tells you which bots to open first.
Frequently asked questions
Should I block GPTBot on my WordPress store?
You can, at no cost to AI visibility: OpenAI documents GPTBot as the crawler for training data, and disallowing it tells OpenAI not to use your content for training [1]. What you must keep allowed are OAI-SearchBot and ChatGPT-User, the bots ChatGPT uses to fetch pages when it answers a question and names its sources.
Does blocking Google-Extended remove me from Google AI Overviews?
No. Google-Extended controls whether your content is used to train and ground Gemini models; Google states that it does not affect a site's inclusion or ranking in Google Search [3], and AI Overviews are part of Search. Blocking Googlebot would remove you from all of them. What blocking Google-Extended can cost is the Gemini app: the same token governs grounding there [3], so a blocked site can drop out of Gemini's answers. Leave it allowed if you want to be cited there.
What is llms.txt and do I need one?
A Markdown file at the site root that lists the site's main pages for language models. Unlike robots.txt it grants or blocks nothing. No major engine has said that it reads it, so it is optional; it costs nothing and the plugin generates it from your content. Crawler access and page content decide citations, not this file.
How do I make an llms.txt file without the plugin?
Use the free llms.txt generator: it scans the site, builds the file from its real URLs, and you upload it to the root so it answers at yourdomain.com/llms.txt. Review the list before publishing and keep it short: the pages you would want an assistant to read first.
How do I know whether an AI bot really visited my site?
Compare the visitor's address with the ranges the bot's operator publishes. The plugin does this for the bots that publish them and marks each visit as verified; bots without published ranges are shown as not verifiable. A user agent string alone can be faked.
I use a cache plugin. Will the visit log still work?
Partly: pages served from the cache do not run PHP, so the counter misses them. Add the web server's access log in the plugin (the "Extra rules and server log" section) and the visits are read from there.
Does this apply to Shopify too?
The reasoning is the same, but Shopify manages robots.txt through the theme's robots template and the CiteProof app checks crawler access from the store check. This guide covers WordPress and WooCommerce, where the plugin writes the rules.
Sources
- [1] Overview of OpenAI Crawlers · OpenAI · 2026 · accessed 2026-10-14
- [2] Does Anthropic crawl data from the web, and how can site owners block the crawler? · Anthropic · 2026 · accessed 2026-10-14
- [3] Google's common crawlers · Google for Developers · 2026 · accessed 2026-10-14
- [4] The /llms.txt file · Jeremy Howard, llmstxt.org · September 2024 · accessed 2026-10-14
- [5] Google's Guide to Optimizing for Generative AI Features on Google Search · Google Search Central · 2026 · accessed 2026-10-14
Read next
- AEO · Answer Engine OptimizationWhat Is AEO? Answer Engine Optimization vs GEO vs SEO
- SEO · WordPressInternal Linking for WordPress & WooCommerce: Find Orphan Pages and Link Them Automatically (2026)
- AEO · TechnicalWhat Is llms.txt? Format, Examples and Who Reads It
CiteProof tracks your brand's visibility across AI answer engines and tells you what to change to get cited. With one rule: the score only moves up after the Verify Bot confirms the fix is actually live.